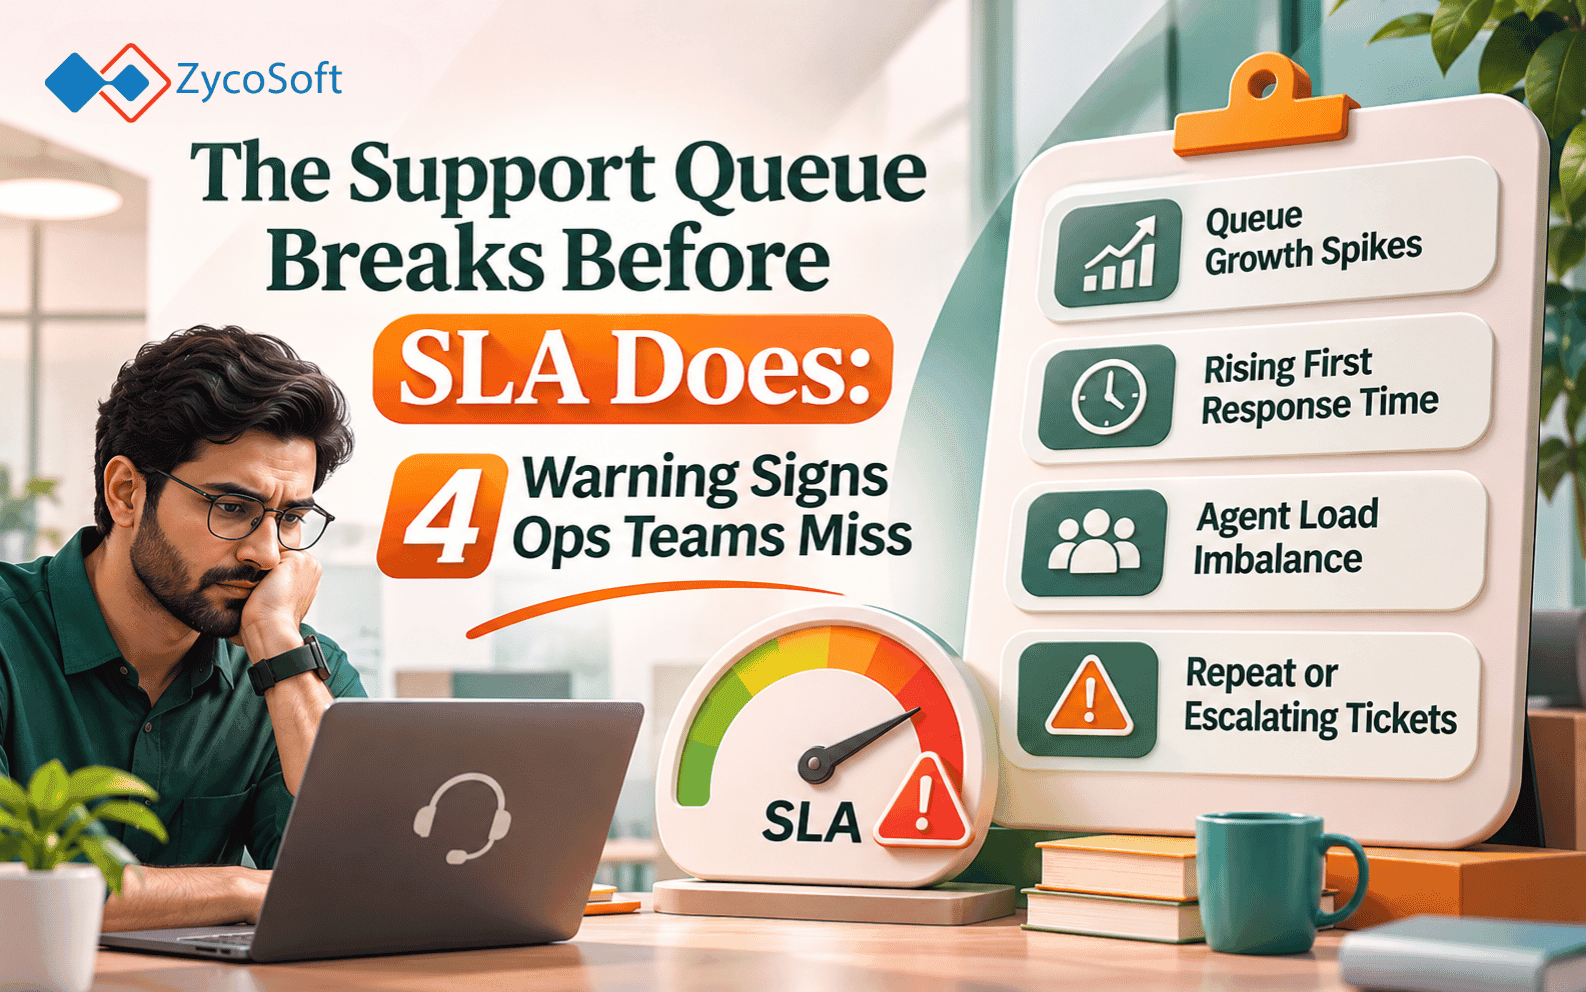
The Support Queue Breaks Before SLA Does: 4 Warning Signs Ops Teams Miss
SLA breach is a lagging indicator. By the time the dashboard flags it, the queue has been degrading for days. Agents knew it. The backlog knew it. Routing rules were misfiring. Nothing tripped an alert because nothing crossed the official threshold.
That is the trap with SLA-only monitoring: it tells you when you have failed, not when failure is building. The four signals below show up in Zendesk, Gorgias, and Intercom before SLA ever trips. Each one has a cause, a shape, and a fix.
1. Routing Failures :
What it looks like: Wrong-team assignments. Billing tickets landing in the technical queue. Shopify order issues routed to general inquiries. In Zendesk, check Views filtered by group for tickets sitting unworked because the assigned team has no context to handle them. In Gorgias, it shows up as tickets with no first reply aging in a queue where volume otherwise looks fine.
What causes it: Routing logic that has not kept pace with how the business changed. A product update, a new return policy, a new 3PL integration: each creates a new ticket type that existing rules do not map correctly. The rules were not wrong when you wrote them. They are stale now.
The fix: Pull tickets resolved in the last 30 days where the first reply came from an agent outside the originally assigned team. If more than 10% required reassignment, your routing has a gap. In Zendesk, audit triggers that have not been modified in over 90 days and cross-reference against ticket types that have changed volume. In Gorgias, review automation rules for conditions referencing product tags or order attributes that may have shifted. While you fix the gaps, add a catch-all rule that flags unmatched ticket types for manual routing.
2. First-Reply Clustering :
What it looks like: Your average first-reply time looks acceptable. But broken down by hour of day, the bulk of first replies cluster in the first two hours of each shift. Tickets that arrive after mid-shift do not get touched until the next shift starts. In Zendesk Explore, this appears clearly when you chart First Reply Time by hour. In Gorgias, the Statistics tab with hourly breakdown shows the same spike-and-silence pattern.
What causes it: Agents are cherry-picking. They work the top of the queue at shift start because those tickets are fresh and easy to context-switch into. Tickets that require more reading or judgment get skipped. The queue sorts by arrival time. Agents do not work it that way.
The fix: This is a queue discipline problem, not a headcount problem. Change your queue sort in Zendesk or Gorgias to surface tickets by age, oldest first. This forces agents to work in order. Set an internal SLA threshold at 80% of your external commitment so you have a buffer before the actual breach. In Gorgias, set up an automation that escalates tickets with no first reply after a set number of hours during business hours. That auto-escalation creates visible pressure to work evenly across the shift.
3. Re-open Rate Climbing :
What it looks like: Solve rate looks fine. Closed ticket volume is healthy. But re-open rate, tickets that get closed and then re-opened by the customer replying again, is trending up week over week. In Zendesk, this is a native report under the Tickets section. In Gorgias and Intercom, you will need to query it manually or pull it via analytics exports.
What causes it: Resolutions that do not actually resolve. A customer asks "where is my order?" and gets a tracking link. The link shows delivered. The customer replies: "It says delivered but I do not have it." Re-opened. The other cause is broad macro usage. If your team is using canned responses in Gorgias or Zendesk macros too loosely, you are closing tickets with answers that do not fit the question.
The fix: Sort re-opened tickets by the original closing agent, then by which macros or tags were applied before close. The pattern will be clear: a small number of agents or macros account for most re-opens. Any macro used more than 100 times in the last 60 days should be audited for accuracy against current policy. Stale macros are silent re-open generators.
4. Queue Age Distribution Skewing Old :
What it looks like: Average handle time looks normal. First reply looks fine. But the full age distribution of open tickets, not the average, shows a long tail. Some tickets are more than five days old. In Zendesk Explore, build a report with ticket age bucketed (0-24h, 24-48h, 48-72h, 3-7 days, 7+ days). In Gorgias, export open tickets with the created_at field and bucket them in a spreadsheet.
What causes it: Agents avoid complex tickets. Orders with partial refunds pending a 3PL response. Subscription cancellations that require manual processing. Anything waiting on another team tends to sit. These tickets do not breach SLA today. They will. A second cause is "waiting on customer" or "pending" tags that never get followed up. The ticket is technically open but off the radar.
The fix: Any ticket over 72 hours old with no agent update in the last 24 hours needs a daily manual review. In Zendesk, set this as a saved view filtered by "Updated more than 24 hours ago AND Status = Open." In Gorgias, create a tag-based view for stale open tickets. For pending tickets specifically: set a maximum hold time. Any ticket in a waiting status for more than 48 hours gets a proactive update to the customer. This prevents silent aging into a breach.
The Pattern Across All Four :
None of these signals are hard to find. They are all visible in the tools you already use. The problem is that most ops teams look at aggregate metrics: average first reply, ticket volume, SLA compliance percentage. Those averages hide the distribution. A 2-hour average first-reply time could mean every ticket is answered in two hours, or it could mean half are answered in 20 minutes and half sit for four hours.
Distribution matters more than average. Ticket age matters more than throughput. Routing accuracy matters more than assignment rate. That is what shows a queue degrading before SLA trips.
If you want to map out where your support queue is fragile before it becomes a breach, ZycoSoft does that work. Book a 30-minute call: zycosoft.com/consultation
Frequently Asked Questions
A support queue SLA warning sign is an operational signal that shows queue degradation before the official SLA threshold is breached. Examples include routing failures, clustering of first replies at shift start, rising re-open rates, and tickets aging in the open queue without agent updates.
In Zendesk, pull all tickets resolved in the last 30 days and filter for cases where the resolving agent was in a different group than the originally assigned group. If more than 10% of tickets required a team reassignment, your routing triggers have gaps that need auditing — especially any triggers not modified in over 90 days.
First-reply clustering is caused by agents cherry-picking fresh, easy tickets at the start of a shift rather than working the queue in order. Tickets requiring more context or judgment get skipped. The fix is enforcing oldest-first queue discipline and setting an internal SLA alert well before the external commitment.
Solve rate measures volume closed. Re-open rate measures resolution quality. A rising re-open rate while solve rate looks healthy is a sign that tickets are being closed with answers that do not actually resolve the customer's issue — often due to stale macros or canned responses that no longer match current policy.
In Zendesk, create a saved view filtered by Open status and Last Updated more than 24 hours ago. In Gorgias, export open tickets with created_at and bucket them by age ranges (0-24h, 24-48h, 48-72h, 3-7 days, 7+ days). Any ticket over 72 hours old with no agent update in 24 hours should be in a daily manual review list.
Escalate when two or more of these signals are trending in the wrong direction simultaneously: routing reassignment rate above 10%, first-reply clustering at shift start, week-over-week re-open rate increase, or more than 5% of open tickets aged over 72 hours. Any single signal is a warning. Multiple signals together mean the queue architecture needs a rebuild.