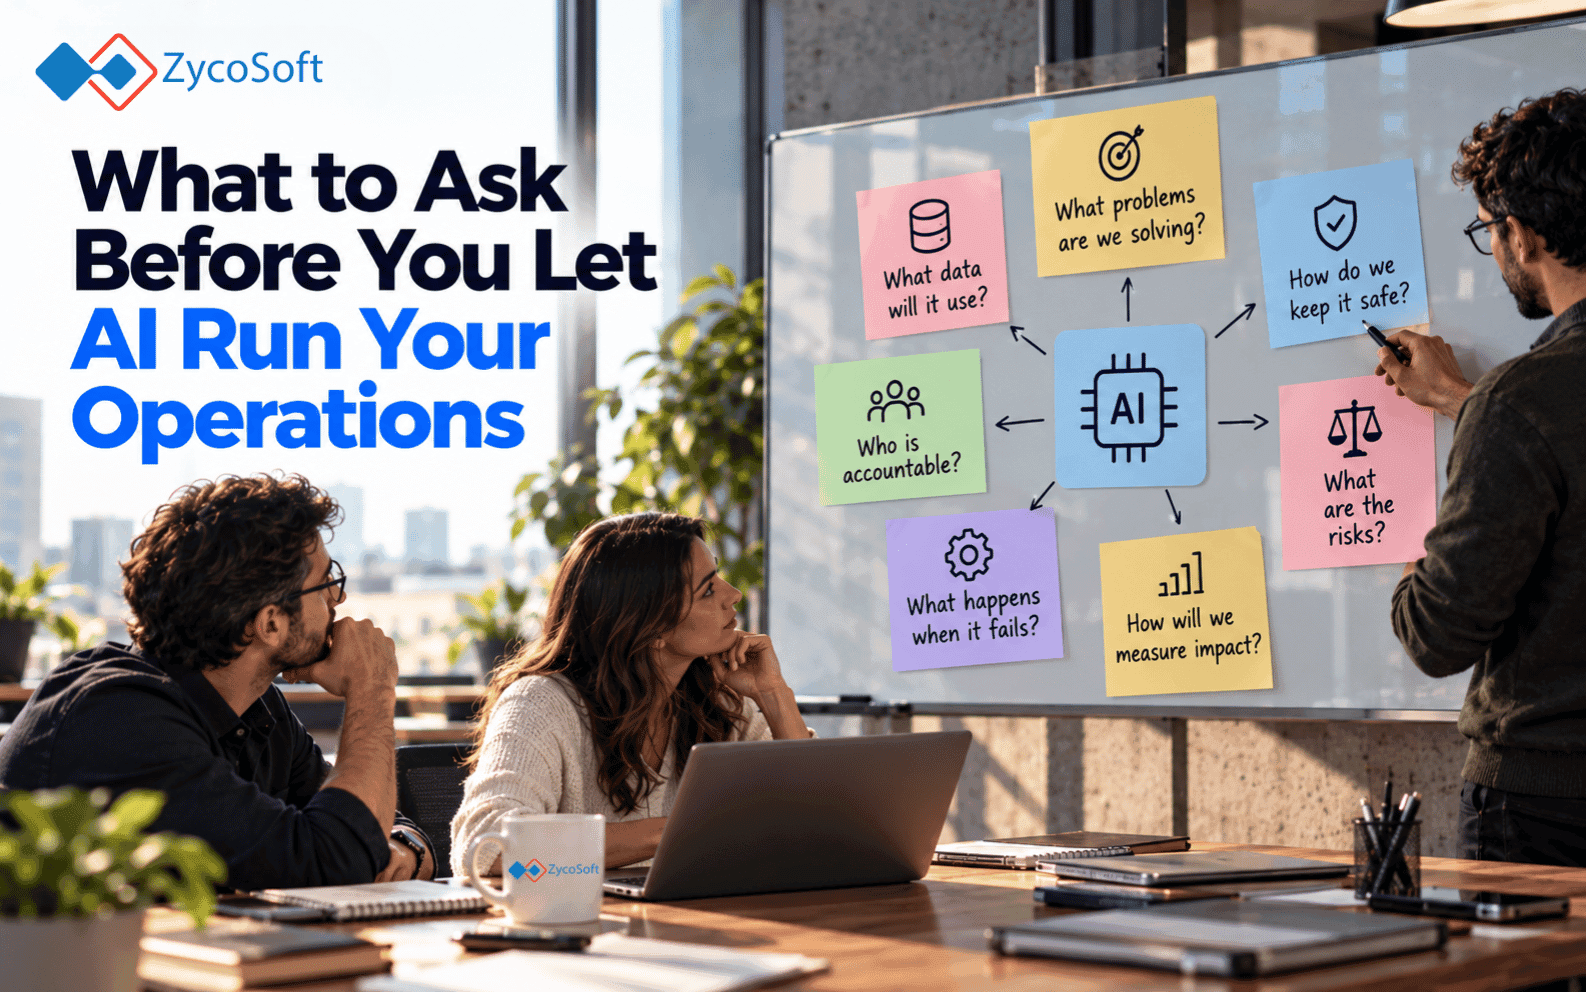
What to Ask Before You Let AI Run Your Operations .
Most AI automation demos look clean. The input is tidy, the output is correct, and the vendor walks you through a workflow that handles exactly the scenario they rehearsed.
What you do not see in the demo: your 3am edge case. The order with a partial refund on top of a loyalty discount. The support ticket where the customer pasted a screenshot instead of typing. The invoice that came in as a scanned PDF with a rotated page.
Production is not a demo. The gap between those two things is where most AI Ops pilots fail.
If you are a founder or ops lead being pitched AI automation right now, the question you should be asking is not "should we automate?" Most teams should. The question is: "How do we know this will not break in production, and what happens when it does?"
This post gives you the checklist. Seven questions. Ask every one of them before you sign anything.
Key takeaways:
- Most AI Ops failures are not model failures. They are accountability, observability, and rollback failures.
- A vendor who cannot describe a real production failure is a vendor who has not run production.
- The gap between a clean pilot and a live deployment is where the real risk lives.
- You can filter bad vendors in under 10 minutes with one question.
- Your ops team should own the automation review before go-live, not the vendor.
The questions most teams skip
1. Who owns it when it breaks?
This is the accountability question, and most teams skip it because the demo went well and everyone is in a good mood.
Before any automation touches your live ops, you need a clear answer to: when this misbehaves, who is responsible for finding out, who gets paged, and who fixes it?
The failure mode here is not technical. It is organizational. An automation vendor who builds the system, hands it over, and disappears has transferred all operational risk to you without transferring any of the context. If something starts silently misfiling orders at 2am, you need to know whose phone rings.
Ask: "If this automation makes 200 wrong decisions overnight, who finds out first and how?"
If the answer involves you manually checking a report the next morning, that is not operations coverage. That is a delayed audit.
2. How does it fail: loudly or silently?
Silent failures are the expensive ones.
A loud failure throws an error, logs something, and stops. A silent failure continues processing, produces wrong output, and keeps going. By the time you catch it, you have 400 mis-routed tickets, or 200 wrong shipping labels, or two weeks of bad data in your CRM.
Ask the vendor: "Can you show me what a failure looks like in your system?" If they show you an error screen, ask what happens when the model processes garbage input and produces confident garbage output with no error.
Good automation is built with explicit failure states. It should know when it does not know. It should route uncertain cases to a human queue rather than forcing a decision. Ask whether that exists, and ask to see it working.
3. Can you roll it back in under 10 minutes?
Rollback is not glamorous. It also does not come up in demos.
If you need to take an automation offline because something went wrong, how long does that take? Who does it? Does rolling it back also undo its recent actions, or just stop future ones? If the automation has been writing to your CRM, your order management system, or your email platform for the past six hours, what is the remediation path?
The honest answer for most automation products is: stopping the automation is fast, reversing its actions is hard or impossible.
That is not automatically a dealbreaker. But you need to know it going in. If the answer is "we can stop the automation in two minutes but you would need to manually review and correct the last N outputs," your ops team needs to be prepared for that.
Ask: "Walk me through exactly what a rollback looks like for this workflow."
4. What are the edge cases that break the happy path?
Every automation has a happy path. The happy path is the scenario the vendor built and tested. It handles the clean input correctly.
Your operations will throw it messy input. Always.
The question to ask: "What happens when the input is unexpected?" Concretely: what happens if a customer submits a form in a language you did not configure? What happens if the data field you depend on comes back empty? What happens if two automations write to the same record at the same time?
You are not looking for "we handle everything." You are looking for: "Here are the specific conditions we validated against, and here is what the system does when it encounters something outside those conditions."
If they cannot list the edge cases they tested for, they have not thought about your production environment. They have thought about their demo.
5. How do you know it is still working next month?
Automations drift. The model that worked well in October may start degrading in November because your input patterns changed, your upstream data source changed its format, or the vendor pushed an update. This is sometimes called model drift, but the more common version is simpler: the data the automation depends on quietly changes, and the automation keeps running against stale assumptions.
Ask: "What does monitoring look like after go-live?" You want to hear about:
- A baseline established at launch (what does good output look like?)
- Ongoing measurement against that baseline.
- Alerting when output quality drops below a threshold.
- A review cadence where a human spot-checks a sample of outputs.
If the answer is "the dashboard shows you throughput," that is activity monitoring, not quality monitoring. Throughput tells you how much the automation is doing. It tells you nothing about whether it is doing it correctly.
6. What does it actually touch?
Blast radius is the term engineers use for "what else breaks if this goes wrong?"
Before any automation goes live, map every system it reads from and every system it writes to. That includes your CRM, your support platform, your order management system, your email service, your Slack, your billing tool. Now ask: if this automation writes bad data to any of those systems, what downstream effects does that create?
An automation that routes support tickets sounds contained. Until it also triggers status update emails to customers, updates a field that your billing integration reads, and creates entries in a reporting dashboard your ops team uses to make staffing decisions. Now a bad run is not just a wrong ticket assignment. It is customer confusion, billing anomalies, and bad headcount data.
Ask: "Can you walk us through every system this automation reads from and writes to?" Then draw the map yourself. You want no surprises when something goes wrong.
7. Is this a demo environment or production data?
The gap between a vendor pilot and live deployment is where most of the real risk lives.
A pilot typically runs on sanitized, controlled data in a staging environment. The vendor sets up a workflow, runs it with clean inputs, and shows you results. That is useful for validating the concept. It is not useful for validating operational readiness.
Before you commit to a live rollout, ask: "Can we run a shadow deployment?" A shadow deployment runs the automation against real production inputs but does not act on the output. Instead, you compare what the automation would have decided against what your team actually decided. Run that for two to four weeks. You will find out very quickly whether the automation handles your edge cases.
If the vendor pushes back on shadow deployment because it delays go-live, ask yourself why they are in a hurry.
What a real AI Ops pilot looks like versus a vendor demo
A vendor demo controls the inputs. A real pilot does not.
In a real pilot, your ops team feeds the automation the actual data it will see in production: messy, incomplete, inconsistent. Support tickets with no context. Orders with custom field combinations. Invoices from customers who format things differently every month.
A real pilot also has a defined success criterion before it starts. Not "we will see how it goes." Something like: "This automation needs to handle 85% of incoming cases without human intervention, and the cases it routes to humans need to be the right ones."
Without a pre-defined success criterion, you are setting yourself up to approve a system based on how the demo felt rather than how it actually performed.
A real pilot also has an exit clause. If performance falls below the threshold at week four, you stop. You do not "give it more time to learn."
The one question that filters vendors fast
If you only have time for one question, ask this:
"Walk me through the last time one of your automations failed in production. What happened, and how did your team find out?"
A vendor who has built and operated real production automations will have this story. It will be specific. It will include what broke, how it was detected (and how long that took), what the remediation was, and what changed in the system afterward.
A vendor who struggles with this question, deflects to hypotheticals, or tells you they have not had production failures is telling you something important: either they have not run real production, or they have not built the observability to know when something goes wrong.
Both of those are problems you will inherit.
Putting it into practice
This week, before your next vendor call, write these seven questions on a page and use them as your filter:
- Who owns it when it breaks?
- How does it fail: loudly or silently?
- Can you roll it back in under 10 minutes?
- What edge cases did you validate against?
- How do you monitor output quality after go-live?
- What does it read from and write to?
- Can we run a shadow deployment before we go live?
You do not need all seven answers to be perfect. You need them to be honest. A vendor who gives you honest, specific, operationally grounded answers to these questions is a vendor who has thought about your problem. A vendor who gives you vague reassurances is a vendor who is selling you the demo.
Your operations are not a demo. They run at 2am, on bad data, with no one watching. Make sure whoever you bring in has actually thought about that.
If you want a team that has run through these questions before the first deployment, talk to us.
Frequently Asked Questions
An AI Ops checklist is a set of questions a founder or ops lead asks before any AI automation goes into production. It covers accountability, failure modes, rollback procedures, edge case handling, output quality monitoring, blast radius, and shadow deployment validation. The goal is to close the gap between a clean vendor demo and real operational readiness.
Run a shadow deployment first. Feed the automation real production inputs without acting on the output. Compare what it would have decided against what your team actually decided. Do this for two to four weeks before committing. Also confirm the vendor can describe a specific production failure from their history, including how it was detected and remediated.
Blast radius refers to every system an automation reads from or writes to, and the downstream effects if it produces bad output. An automation that routes support tickets may also trigger customer emails, update fields your billing integration reads, and affect staffing dashboards. Mapping blast radius before go-live prevents unexpected cascading failures across your stack.
A vendor demo controls the inputs. A real pilot does not. In a real pilot, you feed the automation the actual data it will see in production: messy, incomplete, inconsistent. You define a success criterion before it starts and set an exit clause if performance falls below the threshold. You do not extend the pilot because the demo felt promising.
Production failures usually come from organizational gaps, not model errors. The three most common causes are: no clear owner when something breaks, no alerting when output quality degrades silently, and no rollback plan when the automation needs to be stopped. A clean pilot in a controlled environment does not surface any of these gaps before go-live.